How To Visualize & Customise One way link Research With Python-Search engine marketing Ebook
 [ad_1]
Likelihood is that, you’ve used one of the vital extra fashionable gear similar to Ahrefs or Semrush to research your website’s one-way links.
Those gear trawl the internet to get a listing of web sites linking on your site with a site ranking and different information describing the standard of your one-way links.
It’s no secret that one-way links play a large phase in Google’s set of rules, so it is sensible at the least to grasp your individual website prior to evaluating it with the contest.
Whilst the usage of gear will give you perception into particular metrics, studying to research one-way links by yourself will give you extra flexibility into what it's you’re measuring and the way it’s offered.
And even though it's essential to do many of the research on a spreadsheet, Python has sure benefits.
Rather then the sheer collection of rows it will possibly take care of, it will possibly additionally extra readily take a look at the statistical facet, similar to distributions.
On this column, you’ll to find step by step directions on easy methods to visualize fundamental back-link research and customise your stories by means of making an allowance for other hyperlink attributes the usage of Python.
No longer Taking A Seat
We’re going to select a small site from the U.Okay. furnishings sector for example and stroll thru some fundamental research the usage of Python.
So what's the worth of a website’s one-way links for Search engine marketing?
At its most straightforward, I’d say high quality and amount.
High quality is subjective to the knowledgeable but definitive to Google by means of metrics similar to authority and content material relevance.
We’ll get started by means of comparing the hyperlink high quality with the to be had information prior to comparing the amount.
Time to code.
import re
import time
import random
import pandas as pd
import numpy as np
import datetime
from datetime import timedelta
from plotnine import *
import matplotlib.pyplot as plt
from pandas.api.varieties import is_string_dtype
from pandas.api.varieties import is_numeric_dtype
import uritools
pd.set_option('show.max_colwidth', None)
%matplotlib inline

root_domain = 'johnsankey.co.united kingdom'
hostdomain = 'www.johnsankey.co.united kingdom'
hostname="johnsankey"
full_domain = 'https://www.johnsankey.co.united kingdom'
target_name="John Sankey"
We commence by means of uploading the information and cleansing up the column names to assist you to take care of and faster to sort for the later phases.
target_ahrefs_raw = pd.read_csv(
    'information/johnsankey.co.uk-refdomains-subdomains__2022-03-18_15-15-47.csv')
Checklist comprehensions are a formidable and not more in depth technique to blank up the column names.
target_ahrefs_raw.columns = [col.lower() for col in target_ahrefs_raw.columns]
The record comprehension instructs Python to transform the column title to decrease case for each and every column (‘col’) within the dataframe’s columns.
target_ahrefs_raw.columns = [col.replace(' ','_') for col in target_ahrefs_raw.columns]
target_ahrefs_raw.columns = [col.replace('.','_') for col in target_ahrefs_raw.columns]
target_ahrefs_raw.columns = [col.replace('__','_') for col in target_ahrefs_raw.columns]
target_ahrefs_raw.columns = [col.replace('(','') for col in target_ahrefs_raw.columns]
target_ahrefs_raw.columns = [col.replace(')','') for col in target_ahrefs_raw.columns]
target_ahrefs_raw.columns = [col.replace('%','') for col in target_ahrefs_raw.columns]
Although no longer strictly important, I really like having a rely column as same old for aggregations and a unmarried worth column “undertaking” must I want to crew all of the desk.
target_ahrefs_raw['rd_count'] = 1
target_ahrefs_raw['project'] = target_name
target_ahrefs_raw
-
Screenshot from Pandas, March 2022
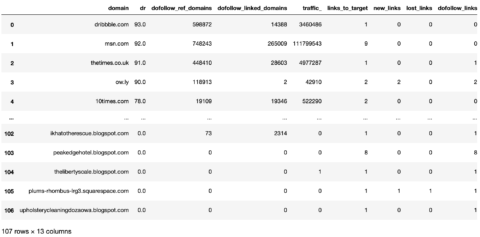
Now we've a dataframe with blank column names.
The next move is to wash the real desk values and cause them to extra helpful for research.
Keep a copy of the former dataframe and provides it a brand new title.
target_ahrefs_clean_dtypes = target_ahrefs_raw
Blank the dofollow_ref_domains column, which tells us what number of ref domain names the website linking has.
On this case, we’ll convert the dashes to zeroes after which solid the entire column as an entire quantity.
# referring_domains
target_ahrefs_clean_dtypes['dofollow_ref_domains'] = np.the place(target_ahrefs_clean_dtypes['dofollow_ref_domains'] == '-',
                                                              0, target_ahrefs_clean_dtypes['dofollow_ref_domains'])
target_ahrefs_clean_dtypes['dofollow_ref_domains'] = target_ahrefs_clean_dtypes['dofollow_ref_domains'].astype(int)


# linked_domains
target_ahrefs_clean_dtypes['dofollow_linked_domains'] = np.the place(target_ahrefs_clean_dtypes['dofollow_linked_domains'] == '-',
                                                           0, target_ahrefs_clean_dtypes['dofollow_linked_domains'])
target_ahrefs_clean_dtypes['dofollow_linked_domains'] = target_ahrefs_clean_dtypes['dofollow_linked_domains'].astype(int)
First_seen tells us the date the hyperlink used to be first discovered.
We’ll convert the string to a date layout that Python can procedure after which use this to derive the age of the hyperlinks in a while.
# first_seen
target_ahrefs_clean_dtypes['first_seen'] = pd.to_datetime(target_ahrefs_clean_dtypes['first_seen'], layout="%d/%m/%Y %H:%M")
Changing first_seen to a date additionally way we will carry out time aggregations by means of month and yr.
This comes in handy because it’s no longer at all times the case that hyperlinks for a website gets obtained day-to-day, even though it might be great for my very own website if it did!
target_ahrefs_clean_dtypes['month_year'] = target_ahrefs_clean_dtypes['first_seen'].dt.to_period('M')
The hyperlink age is calculated by means of taking these days’s date and subtracting the first_seen date.
Then it’s transformed to a host layout and divided by means of an enormous quantity to get the collection of days.
# hyperlink age
target_ahrefs_clean_dtypes['link_age'] = datetime.datetime.now() - target_ahrefs_clean_dtypes['first_seen']
target_ahrefs_clean_dtypes['link_age'] = target_ahrefs_clean_dtypes['link_age']
target_ahrefs_clean_dtypes['link_age'] = target_ahrefs_clean_dtypes['link_age'].astype(int)
target_ahrefs_clean_dtypes['link_age'] = (target_ahrefs_clean_dtypes['link_age']/(3600 * 24 * 1000000000)).spherical(0)
target_ahrefs_clean_dtypes
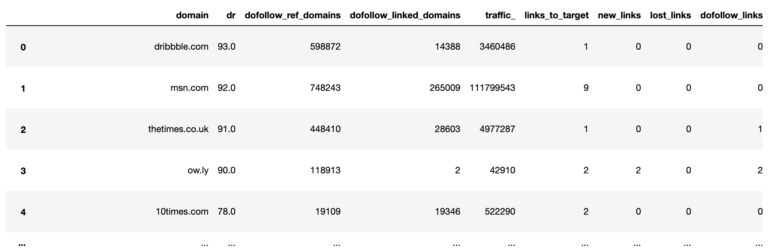 Screenshot from Pandas, March 2022
With the information varieties wiped clean, and a few new information options created, the joys can start!
Hyperlink High quality
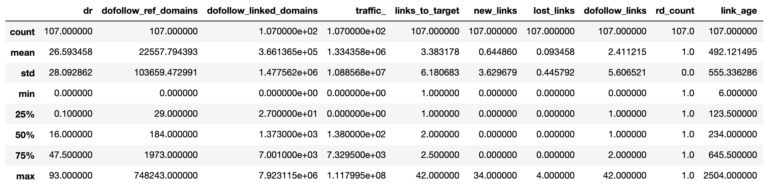
The primary a part of our research evaluates hyperlink high quality, which summarizes the entire dataframe the usage of the describe serve as to get descriptive statistics of the entire columns.
target_ahrefs_analysis = target_ahrefs_clean_dtypes
target_ahrefs_analysis.describe()
 Screenshot from Pandas, March 2022
So from the above desk, we will see the typical (imply), the collection of referring domain names (107), and the adaptation (the twenty fifth percentile and so forth).
The common Area Ranking (identical to Moz’s Area Authority) of referring domain names is 27.
Is that a just right factor?
Within the absence of competitor information to match on this marketplace sector, it’s arduous to grasp. That is the place your revel in as an Search engine marketing practitioner is available in.
On the other hand, I’m sure shall we all agree that it may well be upper.
How a lot upper to make a shift is every other query.
 Screenshot from Pandas, March 2022
The desk above could be a bit dry and tough to visualise, so we’ll plot a histogram to get an intuitive figuring out of the referring area’s authority.
dr_dist_plt = (
    ggplot(target_ahrefs_analysis, aes(x = 'dr')) +
    geom_histogram(alpha = 0.6, fill="blue", boxes = 100) +
    scale_y_continuous() +
    theme(legend_position = 'proper'))
dr_dist_plt
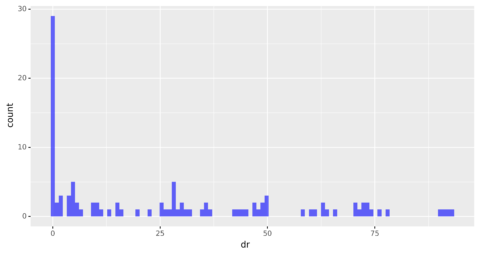 Screenshot from creator, March 2022
The distribution is closely skewed, appearing that many of the referring domain names have an expert ranking of 0.
Past 0, the distribution appears to be like rather uniform, with an equivalent quantity of domain names throughout other ranges of authority.
Hyperlink age is every other essential issue for Search engine marketing.
Let’s take a look at the distribution underneath.
linkage_dist_plt = (
    ggplot(target_ahrefs_analysis,
           aes(x = 'link_age')) +
    geom_histogram(alpha = 0.6, fill="blue", boxes = 100) +
    scale_y_continuous() +
    theme(legend_position = 'proper'))
linkage_dist_plt
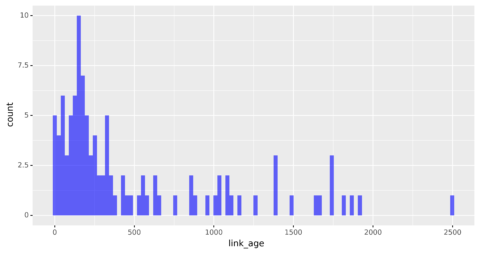 Screenshot from creator, March 2022
The distribution appears to be like extra standard despite the fact that it's nonetheless skewed with the vast majority of the hyperlinks being new.
The most typical hyperlink age seems to be round 200 days, which is lower than a yr, suggesting many of the hyperlinks have been obtained just lately.
Out of passion, let’s see how this correlates with area authority.
dr_linkage_plt = (
    ggplot(target_ahrefs_analysis,
           aes(x = 'dr', y = 'link_age')) +
    geom_point(alpha = 0.4, color="blue", measurement = 2) +
    geom_smooth(approach = 'lm', se = False, color="purple", measurement = 3, alpha = 0.4)
)

print(target_ahrefs_analysis['dr'].corr(target_ahrefs_analysis['link_age']))
dr_linkage_plt

0.1941101232345909
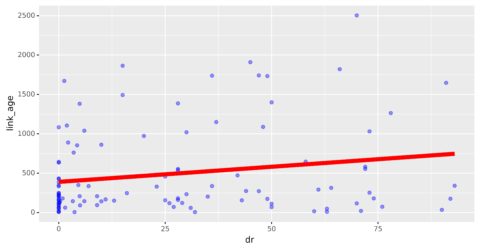 Screenshot from creator, March 2022
The plot (in conjunction with the 0.19 determine published above) presentations no correlation between the 2.
And why must there be?
A correlation would handiest indicate that the upper authority hyperlinks have been obtained within the early section of the website’s historical past.
The cause of the non-correlation will grow to be extra obvious in a while.
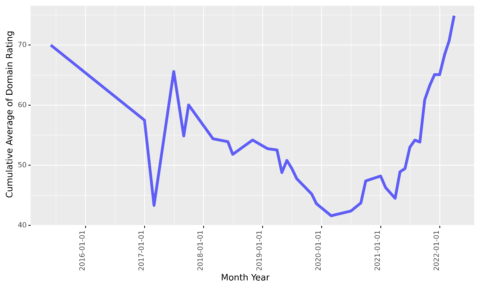
We’ll now take a look at the hyperlink high quality all the way through time.
If we have been to actually plot the collection of hyperlinks by means of date, the time sequence would glance quite messy and not more helpful as proven underneath (no code provided to render the chart).
To reach this, we can calculate a working moderate of the Area Ranking by means of month of the yr.
Observe the increasing( ) serve as, which instructs Pandas to incorporate all earlier rows with each and every new row.
target_rd_cummean_df = target_ahrefs_analysis
target_rd_mean_df = target_rd_cummean_df.groupby(['month_year'])['dr'].sum().reset_index()
target_rd_mean_df['dr_runavg'] = target_rd_mean_df['dr'].increasing().imply()
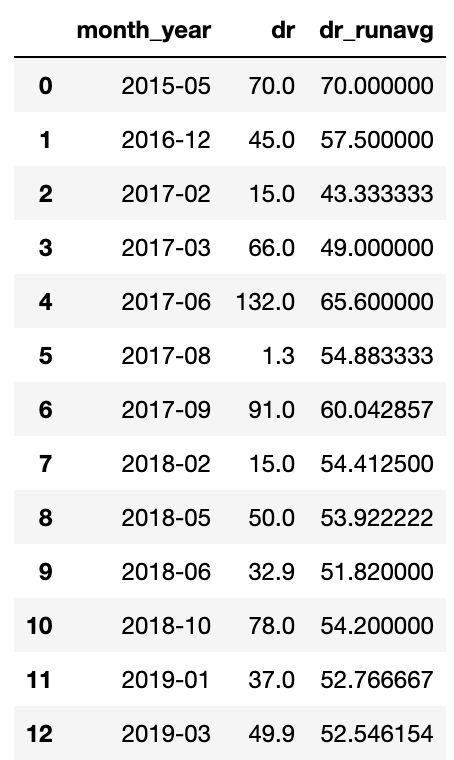
target_rd_mean_df
 Screenshot from Pandas, March 2022
We've a desk that we will use to feed the graph and visualize it.
dr_cummean_smooth_plt = (
    ggplot(target_rd_mean_df, aes(x = 'month_year', y = 'dr_runavg', crew = 1)) +
    geom_line(alpha = 0.6, color="blue", measurement = 2) +
    scale_y_continuous() +
    scale_x_date() +
    theme(legend_position = 'proper',
          axis_text_x=element_text(rotation=90, hjust=1)
         ))
dr_cummean_smooth_plt
 Screenshot by means of creator, March 2022
That is relatively fascinating as it sort of feels the website began off attracting prime authority hyperlinks at the start of its time (almost certainly a PR marketing campaign launching the trade).
It then pale for 4 years prior to reprising with a brand new hyperlink acquisition of prime authority hyperlinks once more.
Quantity Of Hyperlinks
It sounds just right simply writing that heading!
Who wouldn’t need a big quantity of (just right) hyperlinks to their website?
High quality is something; quantity is every other, which is what we’ll analyze subsequent.
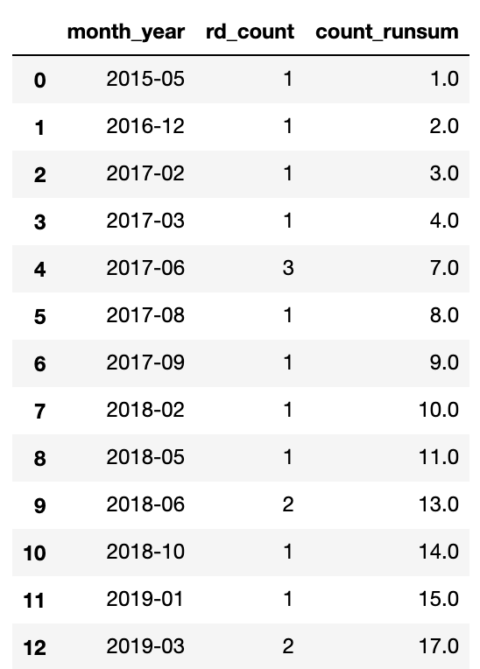
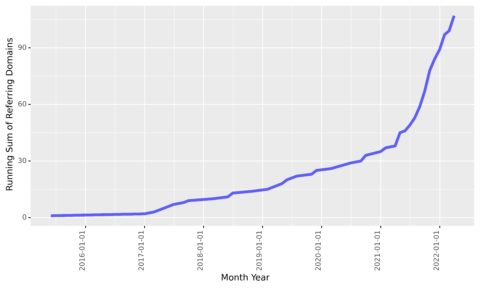
Just like the former operation, we’ll use the increasing serve as to calculate a cumulative sum of the hyperlinks obtained to this point.
target_count_cumsum_df = target_ahrefs_analysis
target_count_cumsum_df = target_count_cumsum_df.groupby(['month_year'])['rd_count'].sum().reset_index()
target_count_cumsum_df['count_runsum'] = target_count_cumsum_df['rd_count'].increasing().sum()
target_count_cumsum_df
Screenshot from Pandas, March 2022That’s the information, now the graph.
target_count_cumsum_plt = (
    ggplot(target_count_cumsum_df, aes(x = 'month_year', y = 'count_runsum', crew = 1)) +
    geom_line(alpha = 0.6, color="blue", measurement = 2) +
    scale_y_continuous() +
    scale_x_date() +
    theme(legend_position = 'proper',
          axis_text_x=element_text(rotation=90, hjust=1)
         ))
target_count_cumsum_plt
 Screenshot from creator, March 2022
We see that hyperlinks obtained at the start of 2017 bogged down however incessantly added over the following 4 years prior to accelerating once more round March 2021.
Once more, it might be just right to correlate that with efficiency.
Taking It Additional
After all, the above is solely the end of the iceberg, because it’s a easy exploration of 1 website. It’s tricky to deduce anything else helpful for making improvements to scores in aggressive seek areas.
Beneath are some spaces for additional information exploration and research.
- Including social media proportion information to each the vacation spot URLs.
- Correlating total website visibility with the working moderate DR over the years.
- Plotting the distribution of DR over the years.
- Including seek quantity information at the host names to look what number of emblem searches the referring domain names obtain as a measure of true authority.
- Becoming a member of with move slowly information to the vacation spot URLs to check for content material relevance.
- Hyperlink pace – the velocity at which new hyperlinks from new websites are obtained.
- Integrating all the above concepts into your research to match on your competition.
I’m sure there are many concepts no longer indexed above, be happy to proportion underneath.
Extra sources:
Featured Symbol: metamorworks/Shutterstock


Comments
Post a Comment